The Problem: Valid JSON Can Still Be Wrong
Ask a model to extract fields from an invoice and it will almost always hand back something that parses cleanly. Every required key is present. Every type matches the schema. Nothing throws a deserialization error. That's the trap: JSON schema validity and factual correctness are two completely different properties, and a model that nails the first tells you nothing about the second.
A model can return a line-item total of $4,230.00 and a grand total of $4,230.00, except the line items actually sum to $4,180.00 — the model transposed two digits reading a scanned PDF. It can return a due date of March 3 for an invoice dated March 15 — an impossible 12-day-early due date that no human would type but a model will cheerfully emit because nothing in the extraction prompt told it dates have to be internally consistent. It can return a purchase order number that doesn't match the vendor on file, a currency code that doesn't match the dollar sign in the document, or a tax amount that's mathematically impossible given the stated rate. None of these are JSON errors. All of them are business errors, and if the only check in the pipeline is "did this deserialize," every one of them sails straight through into your accounting system.
The failure mode that matters here isn't the model hallucinating nonsense — obviously wrong output is easy to catch. It's the model producing output that's locally plausible — a reasonable-looking vendor name, a reasonable-looking dollar amount, a reasonable-looking date — while being globally inconsistent with the other fields on the same document or with rules that have nothing to do with language at all. Catching that requires checks the model was never asked to perform, because they're not inference problems. They're arithmetic, calendar logic, and policy — the kind of thing ordinary code has done reliably for forty years.
The Shape of a Real Solution
The fix is a strict separation of concerns: use the model for what only a model can do — reading unstructured text and mapping it onto a schema — and use deterministic code for everything that can be expressed as a rule. Concretely, that means three layers sitting between extraction and whatever system consumes the result:
- Schema and type validation — does the shape match what the pipeline expects at all? Required fields present, types correct, enums constrained to allowed values. This is the layer most teams already have.
- Deterministic business rules — does the arithmetic add up, is the date sequence possible, do cross-field relationships hold? This is the layer most teams skip, because it feels like it should be the model's job. It isn't.
- Confidence and ambiguity routing — when a rule fails, or when the model itself signals low confidence in a field, is this an automatic reject, an automatic pass, or does a human need to look at it? Treating every rule failure as a hard reject throws away salvageable documents; treating every rule failure as a soft warning defeats the purpose of having rules.
The part that's easy to get wrong is collapsing "missing," "invalid," and "uncertain" into a single boolean. A field the model couldn't find in the document, a field the model filled in with a value that fails a rule, and a field the model extracted but flagged as a low-confidence guess are three different situations that call for three different responses — skip the check, reject or flag the document, or just route it for a second look. A pipeline that only tracks pass/fail loses that distinction the moment it's computed, and loses the ability to explain to a human reviewer *why* a document landed in their queue.
Architecture Overview
The running example below is an accounts-payable intake service: invoices and contracts arrive as PDFs, an LLM extracts structured fields, and everything downstream of extraction is ordinary, testable, deterministic code.
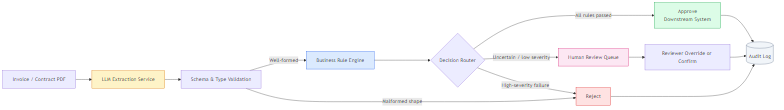
Two things about this diagram are worth calling out. First, the LLM only appears once, at the very start — every box after extraction is deterministic code with no model call inside it, which is exactly what makes the rest of the pipeline unit-testable without mocking anything except that first box. Second, all three terminal paths — approve, review, reject — write to the same audit log. The log isn't a side effect bolted on afterward; it's the mechanism that makes the business rules auditable at all, and it's populated the same way regardless of which path a document took.
Core Implementation: The Validation Pipeline
The extraction result is modeled as a record with nullable fields — a missing field is a legitimate outcome, not an error to paper over with a default. Each business rule implements a common interface and returns a structured result, not a bare boolean, so the pipeline can distinguish a passed check from a failed one from a check that couldn't run because its inputs were missing.
public record LineItem(string Description, decimal Quantity, decimal UnitPrice, decimal LineTotal);

public record InvoiceExtraction(
    string? VendorName,
    string? InvoiceNumber,
    DateOnly? InvoiceDate,
    DateOnly? DueDate,
    string? Currency,
    string? PurchaseOrderNumber,
    IReadOnlyList<LineItem> LineItems,
    decimal? Subtotal,
    decimal? TaxAmount,
    decimal? Total,
    double ExtractionConfidence);

public enum CheckStatus { Passed, Failed, Missing, Uncertain }

public record CheckResult(string RuleName, CheckStatus Status, string Field, string Message);

public enum Decision { Approve, Review, Reject }

public record ValidationReport(
    string DocumentId,
    Decision Decision,
    IReadOnlyList<CheckResult> Checks,
    DateTimeOffset EvaluatedAt);
from dataclasses import dataclass
from datetime import date, datetime
from enum import Enum

@dataclass(frozen=True)
class LineItem:
    description: str
    quantity: float
    unit_price: float
    line_total: float

@dataclass(frozen=True)
class InvoiceExtraction:
    vendor_name: str | None
    invoice_number: str | None
    invoice_date: date | None
    due_date: date | None
    currency: str | None
    purchase_order_number: str | None
    line_items: list[LineItem]
    subtotal: float | None
    tax_amount: float | None
    total: float | None
    extraction_confidence: float

class CheckStatus(str, Enum):
    PASSED = "passed"
    FAILED = "failed"
    MISSING = "missing"
    UNCERTAIN = "uncertain"

@dataclass(frozen=True)
class CheckResult:
    rule_name: str
    status: CheckStatus
    field: str
    message: str

class Decision(str, Enum):
    APPROVE = "approve"
    REVIEW = "review"
    REJECT = "reject"

@dataclass(frozen=True)
class ValidationReport:
    document_id: str
    decision: Decision
    checks: list[CheckResult]
    evaluated_at: datetime
Note what's deliberately absent: there's no field on InvoiceExtraction that collapses to a plain bool IsValid. Validity isn't a property of the extraction — it's the output of running rules against it, and that output needs to carry enough detail to reconstruct the reasoning afterward.
Key Technical Challenge: Distinguishing Invalid, Missing, and Uncertain
The single most common mistake in a hand-rolled validation layer is writing rules that only know how to say yes or no. A rule like "total must equal subtotal plus tax" needs a third and fourth answer: "I can't evaluate this because the total field is missing" and "the model marked this field as a low-confidence guess, so a pass here doesn't mean what it normally means." Each rule has to check its own preconditions before it checks its actual condition.
public interface IBusinessRule
{
    CheckResult Evaluate(InvoiceExtraction invoice);
}

public class TotalArithmeticRule : IBusinessRule
{
    private const decimal Tolerance = 0.01m;

    public CheckResult Evaluate(InvoiceExtraction invoice)
    {
        if (invoice.Subtotal is null || invoice.TaxAmount is null || invoice.Total is null)
            return new("TotalArithmetic", CheckStatus.Missing, "Total",
                "Cannot verify total: subtotal, tax, or total is missing.");

        var expected = invoice.Subtotal.Value + invoice.TaxAmount.Value;
        var diff = Math.Abs(expected - invoice.Total.Value);

        return diff <= Tolerance
            ? new("TotalArithmetic", CheckStatus.Passed, "Total", "Total matches subtotal + tax.")
            : new("TotalArithmetic", CheckStatus.Failed, "Total",
                $"Total {invoice.Total} does not equal subtotal + tax ({expected}); diff {diff:C}.");
    }
}

public class DueDateSequenceRule : IBusinessRule
{
    public CheckResult Evaluate(InvoiceExtraction invoice)
    {
        if (invoice.InvoiceDate is null || invoice.DueDate is null)
            return new("DueDateSequence", CheckStatus.Missing, "DueDate",
                "Cannot verify date sequence: invoice date or due date is missing.");

        return invoice.DueDate >= invoice.InvoiceDate
            ? new("DueDateSequence", CheckStatus.Passed, "DueDate", "Due date is on or after invoice date.")
            : new("DueDateSequence", CheckStatus.Failed, "DueDate",
                $"Due date {invoice.DueDate} precedes invoice date {invoice.InvoiceDate}.");
    }
}

public class LowConfidenceFieldRule : IBusinessRule
{
    private const double ConfidenceFloor = 0.75;

    public CheckResult Evaluate(InvoiceExtraction invoice)
    {
        return invoice.ExtractionConfidence < ConfidenceFloor
            ? new("ExtractionConfidence", CheckStatus.Uncertain, "Document",
                $"Overall extraction confidence {invoice.ExtractionConfidence:P0} is below the {ConfidenceFloor:P0} floor.")
            : new("ExtractionConfidence", CheckStatus.Passed, "Document", "Extraction confidence acceptable.");
    }
}
from abc import ABC, abstractmethod

class BusinessRule(ABC):
    @abstractmethod
    def evaluate(self, invoice: InvoiceExtraction) -> CheckResult: ...

class TotalArithmeticRule(BusinessRule):
    TOLERANCE = 0.01

    def evaluate(self, invoice: InvoiceExtraction) -> CheckResult:
        if invoice.subtotal is None or invoice.tax_amount is None or invoice.total is None:
            return CheckResult("TotalArithmetic", CheckStatus.MISSING, "total",
                                "Cannot verify total: subtotal, tax, or total is missing.")

        expected = invoice.subtotal + invoice.tax_amount
        diff = abs(expected - invoice.total)

        if diff <= self.TOLERANCE:
            return CheckResult("TotalArithmetic", CheckStatus.PASSED, "total",
                                "Total matches subtotal + tax.")
        return CheckResult("TotalArithmetic", CheckStatus.FAILED, "total",
                            f"Total {invoice.total} does not equal subtotal + tax "
                            f"({expected}); diff {diff:.2f}.")

class DueDateSequenceRule(BusinessRule):
    def evaluate(self, invoice: InvoiceExtraction) -> CheckResult:
        if invoice.invoice_date is None or invoice.due_date is None:
            return CheckResult("DueDateSequence", CheckStatus.MISSING, "due_date",
                                "Cannot verify date sequence: invoice date or due date is missing.")

        if invoice.due_date >= invoice.invoice_date:
            return CheckResult("DueDateSequence", CheckStatus.PASSED, "due_date",
                                "Due date is on or after invoice date.")
        return CheckResult("DueDateSequence", CheckStatus.FAILED, "due_date",
                            f"Due date {invoice.due_date} precedes invoice date {invoice.invoice_date}.")

class LowConfidenceFieldRule(BusinessRule):
    CONFIDENCE_FLOOR = 0.75

    def evaluate(self, invoice: InvoiceExtraction) -> CheckResult:
        if invoice.extraction_confidence < self.CONFIDENCE_FLOOR:
            return CheckResult("ExtractionConfidence", CheckStatus.UNCERTAIN, "document",
                                f"Overall extraction confidence {invoice.extraction_confidence:.0%} "
                                f"is below the {self.CONFIDENCE_FLOOR:.0%} floor.")
        return CheckResult("ExtractionConfidence", CheckStatus.PASSED, "document",
                            "Extraction confidence acceptable.")
Each rule's first job is checking whether it can even answer the question it was written to answer. A rule that silently treats a missing field as a pass — or worse, as a zero — produces a report that looks clean while quietly skipping the check that mattered most. Missing has to be a loud, visible outcome, not a default.
Key Technical Challenge: Routing Ambiguous Results
Running every rule produces a list of CheckResults, not a single answer. Turning that list into one of three outcomes — approve, review, reject — needs its own explicit policy, because "one rule failed" doesn't tell you how to react on its own. A missing purchase order number on a low-dollar recurring vendor invoice is a different risk than a failed arithmetic check on a six-figure one-off payment, and the aggregation step is where that distinction gets made.
public class ValidationPipeline
{
    // Rules whose failure can never be auto-approved around.
    private static readonly HashSet<string> HighSeverityRules = new()
    {
        "TotalArithmetic", "DueDateSequence"
    };

    private readonly IReadOnlyList<IBusinessRule> _rules;

    public ValidationPipeline(IReadOnlyList<IBusinessRule> rules) => _rules = rules;

    public ValidationReport Evaluate(string documentId, InvoiceExtraction invoice)
    {
        var results = _rules.Select(r => r.Evaluate(invoice)).ToList();

        var hasHighSeverityFailure = results.Any(r =>
            r.Status == CheckStatus.Failed && HighSeverityRules.Contains(r.RuleName));
        var hasAnyFailureOrUncertainty = results.Any(r =>
            r.Status is CheckStatus.Failed or CheckStatus.Uncertain or CheckStatus.Missing);

        var decision = hasHighSeverityFailure
            ? Decision.Reject
            : hasAnyFailureOrUncertainty
                ? Decision.Review
                : Decision.Approve;

        return new ValidationReport(documentId, decision, results, DateTimeOffset.UtcNow);
    }
}
from datetime import datetime, timezone

HIGH_SEVERITY_RULES = {"TotalArithmetic", "DueDateSequence"}

class ValidationPipeline:
    def __init__(self, rules: list[BusinessRule]):
        self._rules = rules

    def evaluate(self, document_id: str, invoice: InvoiceExtraction) -> ValidationReport:
        results = [rule.evaluate(invoice) for rule in self._rules]

        has_high_severity_failure = any(
            r.status == CheckStatus.FAILED and r.rule_name in HIGH_SEVERITY_RULES
            for r in results
        )
        has_any_failure_or_uncertainty = any(
            r.status in (CheckStatus.FAILED, CheckStatus.UNCERTAIN, CheckStatus.MISSING)
            for r in results
        )

        if has_high_severity_failure:
            decision = Decision.REJECT
        elif has_any_failure_or_uncertainty:
            decision = Decision.REVIEW
        else:
            decision = Decision.APPROVE

        return ValidationReport(document_id, decision, results, datetime.now(timezone.utc))
Why a severity tier, not just a count of failures. A pipeline that rejects on "any failure" will reject a document over a missing PO number with the same finality as a document whose total is off by $4,000. A pipeline that routes everything to review regardless of severity turns the review queue into a dumping ground nobody trusts. The severity tier is a small piece of policy, but it's the piece that makes the automation trustworthy enough that a human reviewer actually reads what lands in their queue instead of rubber-stamping it.
Observability: What to Log and What Not To
The audit trail is the point of this whole exercise — it's what lets you answer "why was this invoice approved" six months later, and it's what regulators and finance teams will ask for first. But the invoice itself often contains data you don't want sitting in a log aggregator indefinitely: vendor banking details, contract terms, sometimes personal information buried in free-text fields.
The ValidationReport as modeled above is already close to the right shape for this: it carries rule names, statuses, and human-readable messages, but the messages above include raw field values for illustration. In production, redact values from the message string and keep them only in the structured fields that have access controls — log "TotalArithmetic failed on field total" with the dollar amounts available via a separate, access-controlled lookup rather than baked into a string that flows into general-purpose logging. Track, as metrics rather than log lines: review queue depth, rejection rate by rule, and — critically — the override rate, meaning how often a human reviewer disagrees with the pipeline's decision. A climbing override rate on one specific rule is the leading indicator that the rule itself has drifted from reality and needs to be revisited, long before anyone files a complaint.
Testing: Proving the Rules Catch What They're Supposed To
The only non-deterministic component in this entire pipeline is the LLM extraction call, and it never needs to be invoked in a rules test — every rule and the aggregation logic takes a plain InvoiceExtraction and is exercised directly. The three scenarios below map straight onto the brief's demonstration cases: a wrong total, an impossible date, and a document that should land in review rather than being rejected outright.
public class ValidationPipelineTests
{
    private static InvoiceExtraction BaseInvoice(decimal subtotal, decimal tax, decimal total,
        DateOnly invoiceDate, DateOnly dueDate, double confidence = 0.95) =>
        new("Acme Supplies", "INV-2201", invoiceDate, dueDate, "USD", "PO-4471",
            new List<LineItem> { new("Widgets", 10, 418.0m, subtotal) }, subtotal, tax, total, confidence);

    [Fact]
    public void WrongTotal_IsRejected()
    {
        var invoice = BaseInvoice(subtotal: 4180.00m, tax: 0m, total: 4230.00m,
            invoiceDate: new(2026, 3, 1), dueDate: new(2026, 3, 31));
        var pipeline = new ValidationPipeline(new IBusinessRule[]
        {
            new TotalArithmeticRule(), new DueDateSequenceRule(), new LowConfidenceFieldRule()
        });

        var report = pipeline.Evaluate("doc-1", invoice);

        Assert.Equal(Decision.Reject, report.Decision);
        Assert.Contains(report.Checks, c => c.RuleName == "TotalArithmetic" && c.Status == CheckStatus.Failed);
    }

    [Fact]
    public void DueDateBeforeInvoiceDate_IsRejected()
    {
        var invoice = BaseInvoice(subtotal: 4180.00m, tax: 0m, total: 4180.00m,
            invoiceDate: new(2026, 3, 15), dueDate: new(2026, 3, 3));
        var pipeline = new ValidationPipeline(new IBusinessRule[]
        {
            new TotalArithmeticRule(), new DueDateSequenceRule(), new LowConfidenceFieldRule()
        });

        var report = pipeline.Evaluate("doc-2", invoice);

        Assert.Equal(Decision.Reject, report.Decision);
    }

    [Fact]
    public void LowConfidenceOnly_RoutesToReviewNotReject()
    {
        var invoice = BaseInvoice(subtotal: 4180.00m, tax: 0m, total: 4180.00m,
            invoiceDate: new(2026, 3, 1), dueDate: new(2026, 3, 31), confidence: 0.6);
        var pipeline = new ValidationPipeline(new IBusinessRule[]
        {
            new TotalArithmeticRule(), new DueDateSequenceRule(), new LowConfidenceFieldRule()
        });

        var report = pipeline.Evaluate("doc-3", invoice);

        Assert.Equal(Decision.Review, report.Decision);
    }
}
import pytest
from datetime import date

def base_invoice(subtotal, tax, total, invoice_date, due_date, confidence=0.95):
    return InvoiceExtraction(
        vendor_name="Acme Supplies", invoice_number="INV-2201",
        invoice_date=invoice_date, due_date=due_date, currency="USD",
        purchase_order_number="PO-4471",
        line_items=[LineItem("Widgets", 10, 418.0, subtotal)],
        subtotal=subtotal, tax_amount=tax, total=total,
        extraction_confidence=confidence)

def make_pipeline():
    return ValidationPipeline([TotalArithmeticRule(), DueDateSequenceRule(), LowConfidenceFieldRule()])

def test_wrong_total_is_rejected():
    invoice = base_invoice(4180.00, 0, 4230.00, date(2026, 3, 1), date(2026, 3, 31))
    report = make_pipeline().evaluate("doc-1", invoice)

    assert report.decision == Decision.REJECT
    assert any(c.rule_name == "TotalArithmetic" and c.status == CheckStatus.FAILED
               for c in report.checks)

def test_due_date_before_invoice_date_is_rejected():
    invoice = base_invoice(4180.00, 0, 4180.00, date(2026, 3, 15), date(2026, 3, 3))
    report = make_pipeline().evaluate("doc-2", invoice)

    assert report.decision == Decision.REJECT

def test_low_confidence_only_routes_to_review_not_reject():
    invoice = base_invoice(4180.00, 0, 4180.00, date(2026, 3, 1), date(2026, 3, 31), confidence=0.6)
    report = make_pipeline().evaluate("doc-3", invoice)

    assert report.decision == Decision.REVIEW
The third test is the one worth paying attention to: it asserts that a low-confidence extraction with otherwise-consistent arithmetic lands in Review, not Reject. Without that assertion, it's easy to accidentally wire the confidence rule into the high-severity set and end up auto-rejecting every slightly-blurry scan — which trains the business to stop trusting the automation within a week.
Technology Choices
Why C# for the rule engine: business rules are, by definition, a place where type safety earns its keep — a rule that accidentally compares a decimal to a string, or forgets to null-check a field, fails to compile rather than failing silently in production. Record types and non-nullable reference types make "this field might legitimately be absent" a compiler-enforced fact rather than a convention.
Why Python works too: dataclasses and an ABC-based rule interface give the same shape with less ceremony, and Python's dynamic typing is less of a liability here than usual because every rule's job is explicit comparisons on explicit fields — there's little room for the kind of implicit coercion that causes trouble elsewhere. Pydantic is a reasonable fit for the schema-validation layer (the first of the three layers) but is deliberately not used for the business-rule layer itself in these examples — rules that encode policy read more clearly as plain functions/classes than as Pydantic validators, which are better suited to shape and type checks than to cross-field business logic.
Engineering Trade-offs
This pattern pays off once extracted data feeds something with real financial or compliance consequences and volume is high enough that a human can't review every document anyway — accounts payable, claims intake, contract compliance. The rule engine is what lets you automate the 80% of documents that are genuinely clean while keeping a human in the loop for the 20% that aren't, instead of choosing between "trust the model fully" and "review everything manually."
It's not worth building for a low-volume process where a human already reviews every document regardless of what the model says — in that case the rule engine adds maintenance burden without removing any human effort. It's also not worth over-building early: start with the two or three rules that correspond to the demonstrated failure modes (arithmetic, date sequence) rather than trying to encode every conceivable business policy before you've seen which ones actually fire in production. A rule nobody's data ever violates is a rule that's just overhead at review time.
Watch for rule drift. Business rules change — payment terms get renegotiated, new vendor categories get added, tax rules shift by jurisdiction. A rule engine that isn't versioned alongside the documents it evaluated becomes impossible to audit: if someone asks "why was this approved eight months ago," you need to know not just what the rules say today but what they said when the decision was made.
Key Takeaways
- JSON schema validity and factual correctness are unrelated properties — a model can satisfy the first while completely failing the second.
- Use the model only for what requires language understanding; enforce everything expressible as arithmetic, date logic, or policy with ordinary deterministic code.
- Track missing, invalid, and uncertain as three distinct outcomes per check, not a single pass/fail boolean — collapsing them loses the information a reviewer needs.
- Aggregate individual check results into a decision using an explicit severity policy, not a raw count of failures — severity is what keeps the review queue meaningful.
- Every rule's result, not just the raw field values, is what belongs in the audit log — it's the reasoning trail, not just the data, that makes the pipeline defensible.
- Build the smallest rule set that covers observed failure modes first; expand only once production data shows which additional checks actually matter.
Interview Questions
Q: Why can't you rely on the LLM to self-report whether its own extraction is correct?
A: A model's confidence or self-assessment is itself a probabilistic output — it can be miscalibrated, and even when well-calibrated it reflects how plausible the output looks to the model, not whether it satisfies rules the model was never told about. Arithmetic and policy checks need to run independently of anything the model says about itself.
Q: What's the difference between a validation layer and a business rule layer, and why keep them separate?
A: Validation confirms the output has the right shape and types — the kind of check a schema can express. Business rules confirm the output is consistent with facts and policy — arithmetic, date ordering, cross-field relationships — which requires domain-specific logic a generic schema can't encode. Separating them means a schema change doesn't require touching business logic, and vice versa.
Q: How do you decide whether a failed check should reject a document, send it to review, or let it pass?
A: By severity, not by failure count. Rules tied to numbers that compound into real financial or compliance risk (arithmetic, date sequencing) are high-severity and should block automatically; rules that flag uncertainty without strong evidence of a problem (confidence floors, soft field mismatches) should route to a human rather than auto-rejecting, so the automation doesn't erode trust by rejecting too aggressively.
Q: What makes a validation pipeline auditable, beyond just logging that something passed or failed?
A: Recording which specific rule ran, its exact result, the message explaining why, and the ruleset version in effect at evaluation time — so months later you can reconstruct not just the decision but the reasoning and the policy that produced it, which is what an audit or a disputed payment actually requires.
Q: Why design explicit human-review routing instead of just having a human check everything the model touches?
A: Reviewing everything doesn't scale and wastes reviewer attention on documents that are genuinely fine. Explicit routing based on rule severity means reviewers only see documents where a specific, named check failed or was uncertain — which also gives them a starting point for what to look at, rather than an undifferentiated stack of paperwork.